Sentry × Anthropic
Sentry x Anthropic: From Days of Debugging to Hours at GPU Scale
20-30% faster incident resolution
Days of crash-loop debugging to hours of resolution
Why it works
The case study earns credibility by grounding every claim in a specific, technically plausible mechanism: custom GPU error tags, job-oriented tracking instead of release-oriented tracking, and Kubernetes preemption events. The before-state is concrete and costly, with named hardware failure modes and a quoted reason the old tool broke. The quotes from Nova DasSarma carry real operational detail rather than praise, which keeps the story from feeling promotional.
Steal this
Frame the before-state around a specific technical constraint the old tool hit (hard throttling limits, no node-level telemetry) rather than a vague pain point. Naming the exact failure mode makes the problem visceral and the switch inevitable.
Members read free
See the full case study
Enter your email to see the full-page screenshot of this case study, and every other one in the library. One email unlocks all of them.
Free. No spam. Unsubscribe anytime.
You're in. Enjoy the library.
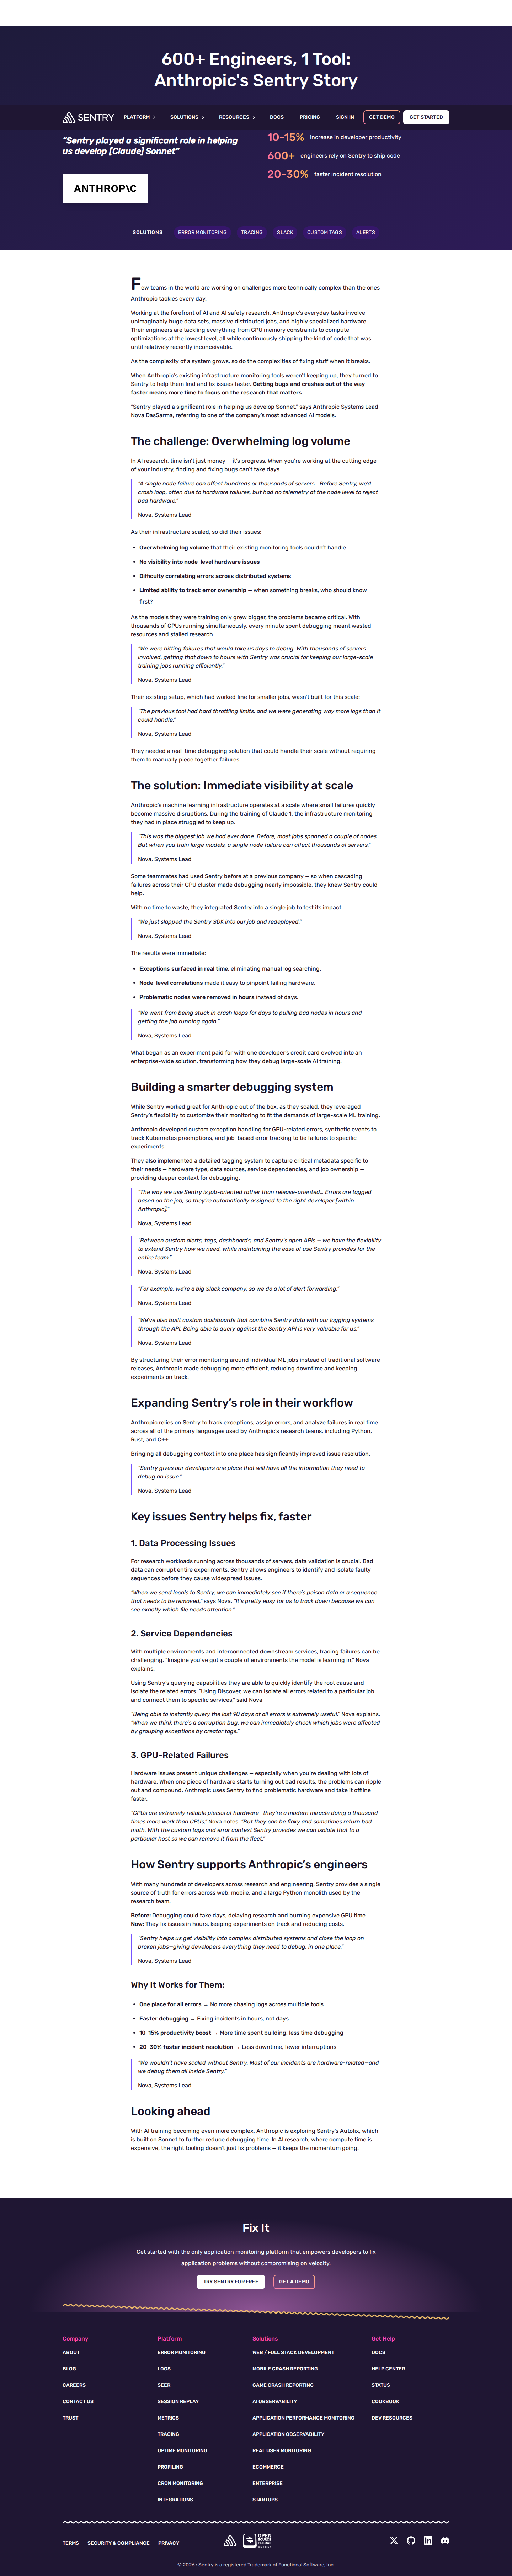 Click to enlarge ↗
This is editorial commentary and curation. The case study, screenshot, and all metrics are Sentry's published work; we link to the source and lead with our analysis.