Sysdig × Bloomreach
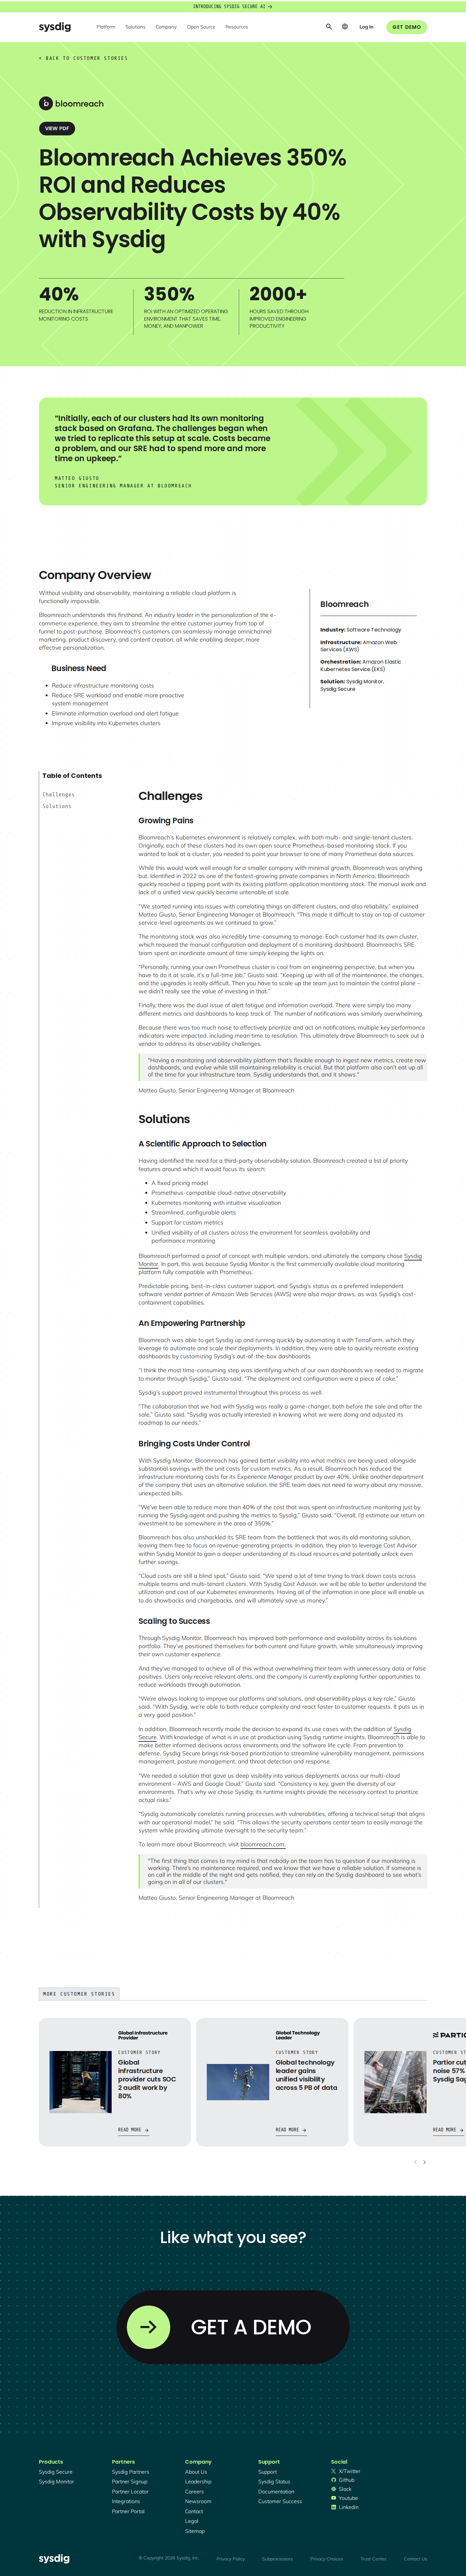
Sysdig x Bloomreach: 40% cost cut and 2000+ hours saved on Kubernetes monitoring
40% reduction in infrastructure monitoring costs
Overwhelmed by maintenance to free to focus on growth
Members read free
Unlock the full breakdown
Enter your email to open every case study in the library: the full screenshot, why it works, and the one thing worth stealing. One email unlocks all of them.
Free. No spam. Unsubscribe anytime.
You're in — enjoy the library.
Why it works
The case study earns its numbers because each figure is tied to a specific product and explained by the customer in their own words. The before-state is concrete: one Prometheus stack per cluster, manual dashboard deployment per customer, and alert fatigue slowing mean time to resolution. The Efficiency tag is clear because the headline leads with costs going down and hours saved, though a Clarity secondary tag is fair given that unified visibility across clusters was a core gap.
Steal this
Anchor the before-state to a specific operational absurdity the reader recognizes: 'running your own Prometheus cluster is a full-time job at scale.' This makes the problem feel lived-in rather than generic, and it lets the ROI numbers land harder.
 Click to enlarge ↗
This is editorial commentary and curation. The case study, screenshot, and all metrics are Sysdig's published work; we link to the source and lead with our analysis.